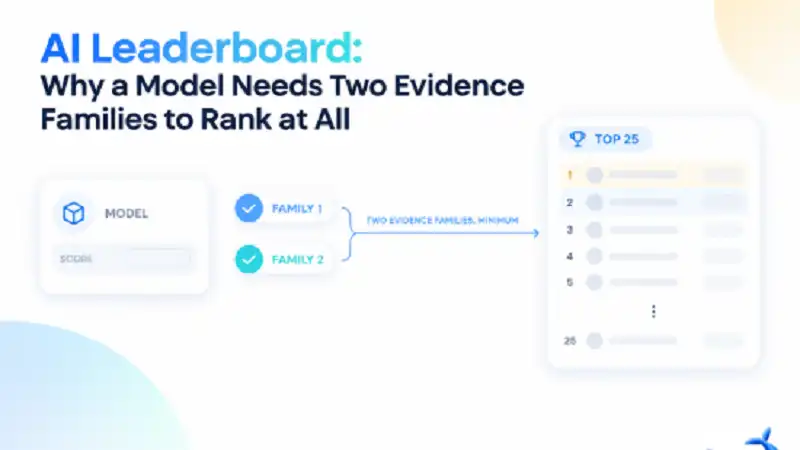
A leaderboard is a claim about who is allowed on the board, and the gate tat decides admission is the part of any ranking most worth reading, because it determines what the table beneath it can even pretend to measure. The OrcaRouter AI leaderboard states its gate in one sentence: a model needs at least two independent evidence families to rank at all, and the board lists the top 25 by composite. That sentence does two jobs at once — it sets a minimum standard of evidence and it fixes the size of the table — and of the two, the minimum standard is the one that deserves the scrutiny, because a single-signal ranking can be produced by accident.
The same page pairs that rule with a second one that is easy to skim past: every number on this page is measured, never self-reported. Taken together, the two sentences are a claim about how the board can and cannot be moved, and that is the claim worth taking apart.
The two-family rule is a barrier, not a weighting
Most leaderboards are scored rather than gated. They blend whatever evidence exists, so a model with one strong signal and nothing else still appears in the table — often near the top. The two-family minimum forbids that outcome outright: a model that appears in only one evidence family has one source of evidence and no way to check it against anything, so it is not allowed to rank at all.
The design point is that two families can disagree, and the disagreement is information. A model with a brilliant independent result but no record yet in a second family cannot be promoted on the strength of a single feed; it has to clear the second family first. The rule blocks the opposite failure just as hard: a model people like but that has no independent measurement cannot park near the top on sentiment alone. The gate makes both errors visible instead of letting either one slip into the table silently.
Independence is the load-bearing word in that sentence. Two numbers produced by the same pipeline are one family wearing two hats. The rule is only meaningful if the two families genuinely fail in different ways, because the entire point of the minimum is that no single source of evidence should be able to carry a rank on its own.
What “measured, never self-reported” rules out
The second sentence is a promise about the first. A two-family minimum is only as strong as what counts as evidence, so the page adds: every number on this page is measured, never self-reported, and no self-reported vendor numbers are used anywhere.
That clause does specific work. If a vendor could submit its own numbers, the gate would let a model through on evidence the vendor chose and measured itself. The page closes that path explicitly. The cost of the rule is real and should be named: a genuinely strong new model with only one family of public evidence is held off the board until the second family materialises. Freshness is designed to keep that wait short — external feeds refresh daily, first-party telemetry is live, and new models enter from external evidence within 48 hours of release. A gate only works if the second family shows up quickly for a model that deserves it; otherwise the barrier quietly becomes a delay.
What the composite number means after standardization
Once a model clears the gate, its score is assembled from signals that arrive on different scales — an Elo figure, a zero-to-one-hundred index, a resolved percentage — so the board standardizes each signal against the current field before it enters the composite. The mapping is published: 50 is the board average, every 15 points is one standard deviation, and values are clamped at the extremes.
That published mapping is what makes the composite readable. A model at 80 sits two standard deviations above the board average. A model at 65 sits one above it. A model at 50 is exactly average. Because the scale is standardized against the field rather than fixed in the abstract, the same score means the same position relative to the field at different moments — which is what keeps the top of the table comparable across a release cycle that changes the field every few weeks.
The same page carries three header statistics that show the board’s shape at a glance: a highest seven-day success rate of 100.0%, a fastest p50 latency of 165 ms, and a highest community win rate of 80.1%, drawn across five evidence sources, all live values that will drift [OURS]. The 165 ms figure is a latency statistic on the board’s own scale; a model page’s time-to-first-token is a different measurement, quoted in seconds, and the two should never be read as the same number.
Six tabs, six re-readings of the same gate
The board is not a single list. It can be read through six category tabs — Text, Coding, Vision, Math, Reasoning and Agentic — and the two-family rule applies the same way inside each. A model that clears only one family of evidence for a category is absent from that tab, whatever its composite says elsewhere. The tabs do not weaken the gate; they re-apply it per category, which is why a model known for one kind of task does not automatically appear everywhere on the board.
What a ranked model’s own page carries
Once a model is on the board, its model page is where the board’s claims become checkable. The current number one, Claude Opus 5.5, sits at the top of the consolidated ranking with a composite of 83.0 [OURS]. Its model page prints its own rate card at $4.00 per million input tokens and $20.00 per million output tokens [VENDOR], a 1M-token context window, and its own production telemetry block, and it describes the model as particularly strong at multi-step changes in large codebases and code review. The board entry and the model page are the same evidence read twice: one tells you where the model ranks, the other tells you what you would pay to run it and what it is for.
The takeaway
A leaderboard’s admission gate deserves more scrutiny than its scores, because a score you can argue with is still a score, while a model admitted on one unverifiable signal poisons every row beneath it. This board gates entry on two independent evidence families, lists only the top 25 by composite, standardizes every signal so that 50 is the board average and 15 points is one standard deviation, and states that every number is measured rather than self-reported. Read it as a claim about evidence discipline, and the composite becomes a second-order detail: the rule about who is allowed to appear is doing the heavy lifting.
Sourcing note: the two-family entry rule, the top-25 board size, the standardization rule, the freshness statement, the no-self-reported-numbers clause, the six category tabs and the three header statistics are read from the OrcaRouter leaderboard on 2026-10-15, where the platform’s own telemetry is [OURS] and no third-party figures are cited [OURS]. The Claude Opus 5.5 rate card is the provider’s published rate as printed on the model page [VENDOR]; the composite rank and the model page’s telemetry block are our own [OURS]. Latency and success-rate figures are live seven-day values and will drift. Read 2026-10-15.